Une interview avec l'expert ML de Spyrosoft : le lauréat du concours Kelp Wanted


The ability to make effective use of data is now not only a key element of development, but also often a determinant of success. As a leading technology company, we are characterised not only by innovation in the field of IT solutions, but also by an impressive team of experts!
Nous avons donc le plaisir de vous présenter Michal Wierzbinski, notre Lead Data Scientist, qui a remporté la deuxième place au concours Kelp Wanted. Dans cette interview, nous examinons le parcours de Michal vers la victoire au concours et les opportunités offertes par le monde en évolution dynamique de l'analyse de données et intelligence artificielle.
Quel était l'objectif principal de la compétition, et quelle solution de ML avez-vous développée ?
La compétition visait à développer des algorithmes capables de détecter la présence ou l'absence de forêts de varech sur les images satellites Landsat. Cette tâche exigeait des compétences techniques machine learning, des connaissances en traitement d'images et une compréhension approfondie du contexte environnemental et des subtilités des données géospatiales.
Kelp forests are crucial ecosystems, rich in biodiversity and serving various ecosystem functions, such as providing habitat for fish or coastal communities. However, environmental changes increasingly threaten kelp forests, prompting organisations like Kelp Watch to take protective and monitoring actions to safeguard these ecosystems.
As part of the competition, organisers wanted to see how others approached this problem to gain new insights into monitoring kelp forests. They provided participants with satellite data from the Landsat platform, which has been collecting satellite images since 1972. This data was used to conduct semantic segmentation analysis, allowing for the identification of areas of kelp forests in satellite images. I must admit that I had prior experience working with this type of data for our clients on projects such as a platform on Azure for monitoring mining areas and their environmental impact, segmentation of mining site areas, land cover classification and change detection. This experience allowed me to effectively utilise various techniques in analysing these images. I ultimately developed a precise model, the second-best out of 671 submissions worldwide, with score DICE de 0,7318.
The topic of the model itself is technical. It is based on a neural network and the U-net architecture, which is widely popular worldwide, especially in semantic segmentation. The features for this network are derived from the EfficientNet encoder. During the competition, I spent most of the time exploring the data. Initially, I used the U-Net architecture with ResNet-50 encoder, making it easier for me to start work, achieve reasonable results, and provide opportunities for further optimisation. Throughout the first half of developing my solution, I was mainly experimenting with the data. I split the data into 10-fold cross validation sets.
Cependant, j'ai rapidement découvert que les données fournies n'étaient pas suffisamment propres – comme nous aimons le dire dans le secteur : données de mauvaise qualité, résultats de mauvaise qualité. J'ai dû enrichir ces données. Au cours de ce processus, j'ai remarqué qu'il y avait doublons in the dataset. Although they cover the same area, they are observed from different revisit times and orbits, leading to the data leakage across the folds. There were even up to 200 duplicates for one area, requiring the application of embedding techniques and cosine distance. I reduced similar images into similar groups from 5000 à 3000 emplacements uniques.
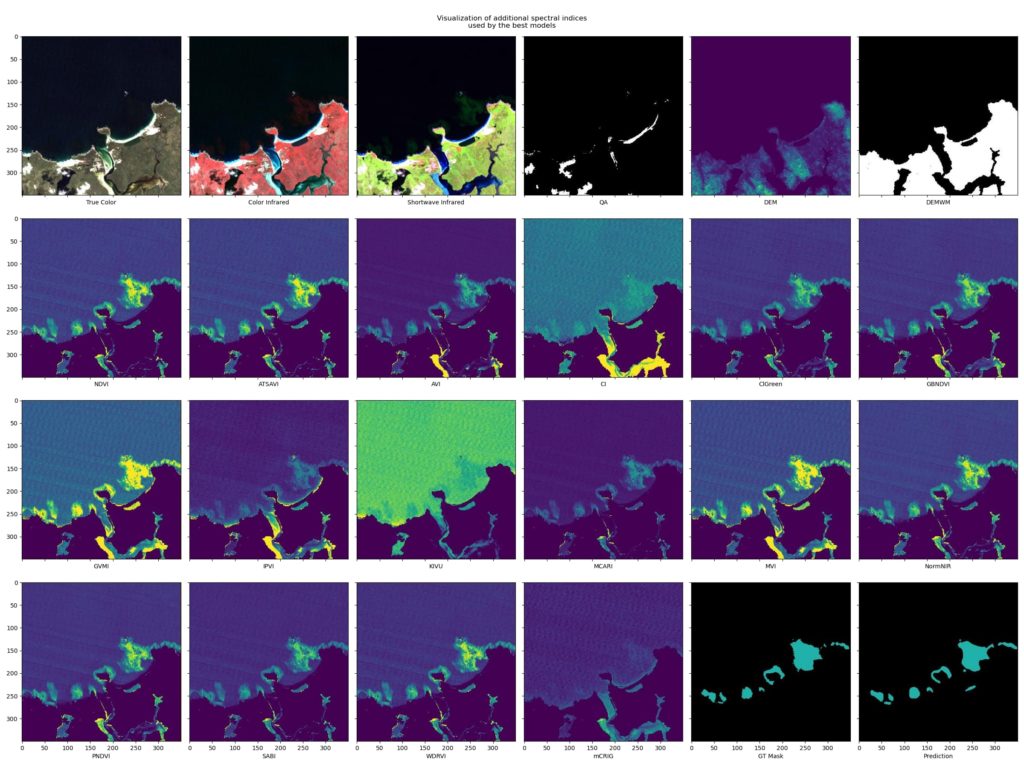
About two fifths of the entire data set consisted of open water images. After generating the groups, I felt more confident, as if my model performed well on the training and validation sets, it means the model will be able to generalise to other areas. It’s worth noting that as participants, we had access to metrics calculated on a subset of the test dataset, the final scoring was being done on remaining portion of the dataset. During experiments, I tried various loss functions and data normalisation techniques, but the most significant success turned out to be adding separate spectral indices. Satellite images have various spectral data, such as near-infrared, short wave infrared, etc. I used them to create indices that are commonly used for detection of stressed vegetation or the creation of water mask. After a few days of training, it turned out that a combination of an additional 17 indices worked well and were crucial for improving the model’s effectiveness. I also applied model ensemble techniques to improve results. Each pixel is classified as 1 or 0, indicating the presence or absence of kelp forest, and then an appropriate value is assigned through weighted averaging. This strategy further improved the model’s results and achieved significant accuracy in kelp forest segmentation on satellite images.
D'où est venue l'idée de développer une telle solution ?
The idea for developing such a solution mainly stemmed from my previous experience working with satellite data and numerous projects I had undertaken at Spyrosoft and throughout my professional career. Having domain knowledge in this field, I decided to leverage my expertise to devise this comprehensive solution. It’s worth noting that my iterative approach played a crucial role. Initially, I approached the project straightforwardly, focusing on implementing basic elements. Then, gradually and methodically, I expanded the solution, experimenting with various techniques and methods to achieve the best results. Thanks to this approach, I successfully developed an effective solution that met the set goals and expectations regarding the development of the kelp forest detection algorithm.
Quels défis techniques avez-vous rencontrés lors du développement de l'algorithme de détection de la couverture d'algues sur les images satellitaires, et quelles mesures avez-vous prises pour y remédier ?
I encountered several significant technical challenges while developing the algorithm for detecting kelp cover on satellite images. The first was the issue of data quality and segmentation masks, which could have been more optimal. The metric used for evaluation did not exceed 75%, ce qui indique clairement l'imperfection du processus d'étiquetage des données.
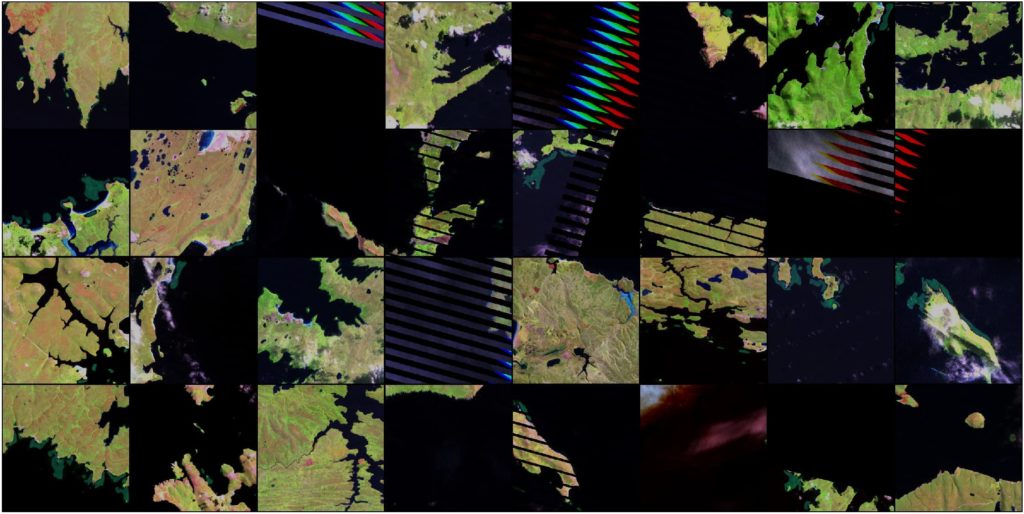
Additionally, Landsat data suffered from various imperfections, including striping in some visualisations caused by satellite malfunction and being clipped into a specific tile grid. These introduced additional challenges, especially in the context of lacking information about geolocation of the tiles. To address these issues, it was necessary to employ ‘area of interest’ grouping techniques to achieve the most precise results possible.
Quelles autres façons d'utiliser l'apprentissage automatique pour la surveillance environnementale ?
Assessing the state of the environment through machine learning offers diverse opportunities for monitoring and protecting ecosystems. ML can be used to predict levels of air pollution based on sensor data and satellite imagery, monitor water quality, predict threats to water resources, or monitor mining areas to understand the extent of exploration of various minerals and their potential extraction. Additionally, analysing data from drones, satellite images, and sensors can help in precision agriculture industry or in forestry services by monitoring the health of forests, identifying areas at risk of droughts, fires and floods, and protecting endangered animal species.
Machine learning can aid in predicting natural disasters through the analysis of historical data on phenomena such as earthquakes and hurricanes. Additionally, it facilitates monitoring climate change by examining meteorological data and levels of greenhouse gases. This technology further assists in biodiversity conservation through the analysis of species occurrence data and their habitats.
Quels bénéfices nos clients utilisant le ML pour l'analyse d'images satellitaires peuvent-ils apporter ?
Using machine learning for satellite image analysis can bring numerous benefits to our clients. Employing machine learning technology to analyse data from social media feeds enables rapid identification of various news categories, allowing for the automatic assignment of satellite data acquisition from these areas within minutes, providing clients with a lightning-fast response to the latest events, and optimising resource utilisation. Through ML algorithms, automatic processing of satellite images and generation of precise maps is possible, which is particularly useful in urban planning, monitoring environmental changes, and in the agricultural sector for crop optimisation. Machine learning systems regularly scan satellite images, detecting changes in terrain and enabling a quick response to threats or opportunities.
Additionally, satellite image analysis using ML supports monitoring natural resources such as forests, rivers, or water reservoirs, which can be utilised for resource management and combating illegal practices, such as deforestation. It’s worth noting that satellite data can be used to forecast atmospheric phenomena such as storms, floods, or droughts, aiding in preventive actions and crisis management. Monitoring infrastructure through ML allows for the automatic detection of damages or failures, enabling swift intervention and repair. Satellite images can also be used to monitor endangered areas and allow a quick response to potential security threats.
Quels défis environnementaux considérez-vous comme les plus urgents aujourd'hui, et comment l'apprentissage automatique peut-il aider à les relever à l'avenir ?
In contemporary environmental challenges, utilising technology, including machine learning, becomes crucial in solving these problems. One of the most pressing issues is climate change, resulting in rising global temperatures, extreme weather phenomena, the loss of glaciers, rising sea levels and food security issues, especially in less developed countries.
ML can assist in forecasting and monitoring these changes by analysing large amounts of climate data. Additionally, the depletion of natural resources such as water, soil, forests, and minerals threatens ecological balance and sustainable development. The use of machine learning algorithms can contribute to optimising the consumption of these resources across various sectors, allowing for more sustainable utilisation.
Air, water, and soil pollution are also significant environmental challenges. ML-based systems can monitor pollutants and identify their sources, enabling practical corrective actions. This technology can also be utilised to analyse biodiversity data, identify areas requiring protection, and take action to preserve biological diversity.
De plus, l'apprentissage automatique peut soutenir le développement d'innovations durables, telles que les sources d'énergie renouvelables et des processus de production plus efficaces, réduisant ainsi l'impact environnemental négatif de l'activité humaine.
Vous recherchez un partenaire en technologie géospatiale ?
En savoir plus sur notre services géospatiaux ou contactez-nous à l'aide du formulaire ci-dessous.
Discutons de la manière dont notre équipe d'experts peut vous accompagner dans votre prochain projet !


arrow_circle_rightContactez-nous
Contactez-nous et découvrez comment nous pourrions soutenir votre projet géospatial

arrow_circle_right Nos articles