حلول واجهة الإنسان والآلة متعددة الوسائط: الجمع بين اللمس والصوت باستخدام الذكاء الاصطناعي

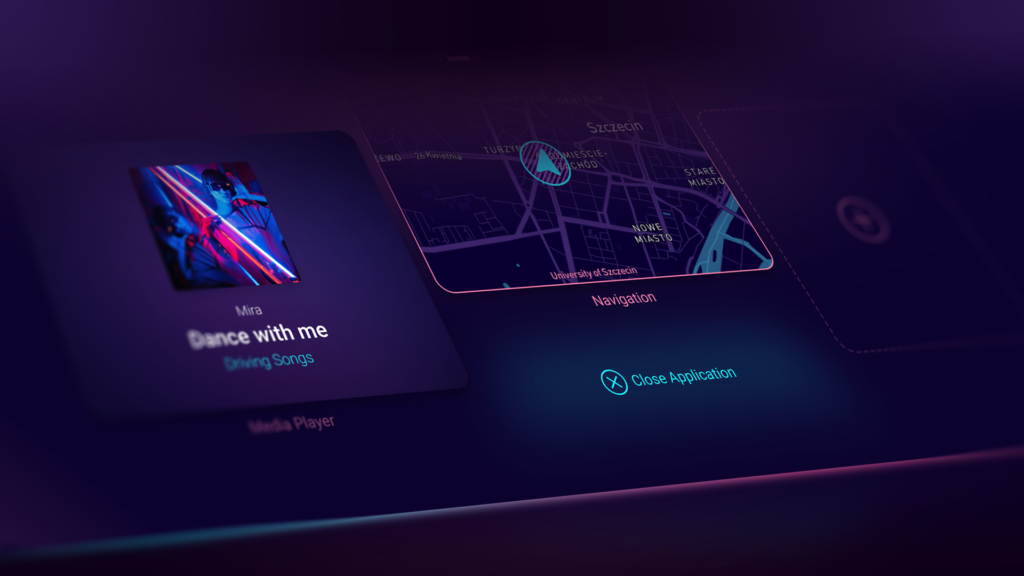
Multimodal HMI describes a system that allows users to interact through more than one input or output channel, typically touch and voice. Instead of limiting control to physical buttons or touchscreens, multimodal interfaces enable speech, gesture and touch to work together, letting people communicate in the way that feels most natural at any given moment.
Touch remains unmatched for precision and direct manipulation, while voice provides freedom and accessibility. When combined, they balance each other’s limitations and create interactions that are intuitive, personalised and safer, particularly in contexts where attention and hands are already occupied.
في المركبات، تعزز هذه التركيبة قابلية الاستخدام والسلامة معًا. يمكن للسائق أن يقول، "انتقل إلى أقرب شاحن" or «اضبط درجة الحرارة على 22 درجة» مع إبقاء أعينهم على الطريق، ثم إجراء تعديلات دقيقة باللمس عند التوقف. يحدد هذا التفاعل المرن والقابل للتكيف معيارًا جديدًا في تجربة المستخدم.
نظراً لأن المساعدين الرقميين مثل Alexa وSiri وGoogle Assistant دربوا المستخدمين على توقع تفاعلات صوتية طبيعية، فإن هذا التوقع نفسه يمتد الآن إلى المركبات والأنظمة الصناعية.
بالنسبة لنا فيSpyrosoft Synergy، تمثل واجهة الإنسان والآلة متعددة الوسائط الخطوة التالية المنطقية في إنشاء واجهات تتكيف حقًا مع احتياجات الإنسان بدلًا من إجبار المستخدمين على التكيف مع التكنولوجيا.
لماذا يغيّر الذكاء الاصطناعي والنماذج اللغوية الكبيرة طريقة تفاعلنا
وُجدت الواجهات الصوتية منذ عقود، لكنها كانت حتى وقت قريب قائمة على القواعد وجامدة.
كانت تتعرف فقط على الأوامر المحددة مسبقًا وتفشل عندما تتغير الصياغة. لقد غيّر الذكاء الاصطناعي هذا المشهد تمامًا.
يمكن للأنظمة الحديثة المدعومة بنماذج اللغة الكبيرة (LLMs) تفسير القصد والسياق والعاطفة. فهي تفهم تنويعات الصياغة، وحتى العامية أو الجمل غير المكتملة. فعندما يقول السائق «أشعر بالبرد،» لا يحتاج المساعد إلى أرقام صريحة. فهو ببساطة يرفع درجة حرارة المقصورة. وإذا أضافوا لاحقًا «لي وحدي فقط،» الأداء والتحسين – لماذا تُعد السرعة مهمة
This flexibility means users no longer need to memorise command syntax. They can talk as they would to another person. LLMs maintain dialogue context across turns, enabling follow-up questions and compound requests. For example, "ابحث عن مطعم سوشي جيد في طريق العودة إلى المنزل واحجز طاولة لشخصين" يُفعّل سلسلة من المهام: البحث والتصفية والحجز وضبط الملاحة، كل ذلك من طلب صوتي واحد.
شركات تصنيع السيارات تتبنى بالفعل مثل هذه الأنظمة.
مرسيدس-بنز, for instance, has integrated ChatGPT into its in-car assistant to handle more conversational prompts, understand open-ended questions and provide detailed answers. The result is a new kind of human–machine partnership: one that listens, interprets and assists proactively rather than passively executing commands.
We use similar natural-language processing technologies in our AI and Machine learning projects to build assistants capable of understanding nuance and adapting over time, bringing truly intelligent interfaces into the driver’s seat.

بناء البنية المعمارية: كيف يعمل اللمس والصوت معاً
خلف كل تجربة متعددة الوسائط بديهية توجد بنية معمارية متعددة الطبقات تنسق كلا نمطي الإدخال بسلاسة.
يبدأ النظام بالكشف عن المدخلات والمحفزات. كلمة التنبيه "Hey BMW" or a push-to-talk button signals the start of speech input, while the touch layer registers gestures and taps. Both channels feed into a central interaction manager that coordinates timing and context.
The speech-to-text (STT) engine transcribes spoken words into text with minimal latency. High-accuracy cloud models are often combined with smaller on-device engines that handle frequent commands offline.
تأتي بعد ذلك مرحلة فهم اللغة الطبيعية (NLU) أو المعالجة المباشرة عبر نماذج اللغة الكبيرة (LLM)، والتي تستخرج نية المستخدم والمعاملات ذات الصلة. على سبيل المثال، “اضبط المقصورة على درجة حرارة مريحة وشغّل موسيقى الجاز” ينتج نيتين: ضبط المناخ وبدء تشغيل الموسيقى.
The dialogue manager then uses session context to decide the best response, asking for clarification if needed. The orchestrator maps intents to specific system actions through APIs that interface with vehicle functions. Finally, the feedback layer confirms success through speech, visual animations or tactile feedback.
تستخدم المعمارية المصممة جيداً نهجاً هجيناً: معالجة سريعة على الجهاز للإجراءات الروتينية وذكاء سحابي للاستدلال المعقد. وبهذه الطريقة، أوامر مثل “شغّل المساحات” تعمل على الفور حتى بدون اتصال، بينما الاستعلامات الأوسع، مثل «كيف حال الطقس على طول مساري؟»، استفد من بيانات السحابة.
إدارة السياق لتفاعل أكثر ذكاءً
أكثر جانب إنساني في أي واجهة ذكاء اصطناعي هو قدرتها على فهم السياق.
يتيح السياق للنظام تفسير اللغة الغامضة وتذكّر المحادثات الأخيرة وتكييف الردود مع الموقف.
هناك عدة طبقات رئيسية للسياق:
- سياق الجلسة نقدم لعملائنا التعاون وفق عدة نماذج، تشمل:
سياق المستخدم يتذكر التفضيلات الفردية مثل وضعية المقعد وإعدادات المناخ ونمط الموسيقى.
- سياق المركبة يتضمن بيانات الحالة – ما إذا كانت السيارة في حركة، وأي المقاعد مشغولة، أو في أي وضع تعمل.
- السياق البيئي يراعي العوامل الخارجية مثل الموقع والطقس والوقت من اليوم.
معاً، يمكّنان سلوكاً يبدو طبيعياً. إذا قال الراكب «أشعر بالبرد الشديد» : يمكننا تقديم المشورة لك بشأن حل تقني، وإعداد التصاميم، وبناء إثبات المفهوم. «لقد رفعت درجة حرارة الراكب إلى 24 درجة وشغّلت مدفأة المقعد.»
Managing context requires careful balance. Retaining too much information can cause confusion or privacy risks, while too little breaks continuity. Best practice is to maintain short-term memory for dialogue and store long-term preferences locally in a secure, encrypted form.
دعم تكامل إنترنت الأشياء وتعلّم الآلة
بغض النظر عن مدى تطور الذكاء الاصطناعي، فإن الأداء يحدد رضا المستخدم. في الأنظمة التفاعلية، تبدو التأخيرات التي تتجاوز ثانيتين بطيئة وتقاطع تدفق التفكير.
To meet these expectations, engineers optimise every stage of the voice pipeline. Wake-word detection must respond in under 200 milliseconds. Speech-to-text conversion should finish within half a second. The overall round-trip, from command to confirmation, should stay below one and a half seconds for simple actions.
This is achieved through on-device inference for core commands, model optimisation (distillation, quantisation and pruning) to reduce compute load, and dynamic prioritisation that temporarily reallocates resources from background tasks to voice processing.
بنفس القدر من الأهمية هي الاستجابة المُدركة. حتى عندما يستغرق الإجراء وقتاً أطول، فإن التغذية الراجعة الفورية مثل نبرة الاستماع أو إقرار قصير («نعمل على ذلك…») يطمئن المستخدمين بأن النظام نشط.
After deployment, continuous monitoring ensures performance doesn’t degrade. Engineers track metrics such as intent accuracy, latency and error recovery rates. These insights feed back into retraining cycles, forming an ongoing improvement loop, a process similar to how we manage model optimisation in our AI deployments.
دمج نماذج الكلام واللغة
Integrating voice and language models within the HMI pipeline ensures that speech flows smoothly into action. The chain runs from wake-word detection to speech transcription, language understanding, intent mapping and API execution. Each link must use well-defined interfaces so individual modules can evolve independently.
Testing under realistic driving conditions is critical. Cars are challenging acoustic environments: engine vibration, wind and passenger chatter can interfere with recognition. Engineers must tune microphone arrays, apply noise suppression and test across a range of accents and languages.
لا يقل أهمية عن ذلك التزامن بين الوسائط. عندما يقول المستخدم «زيادة درجة الحرارة،» the visual UI should update instantly, showing confirmation. If an instruction is unsafe or not permitted, the assistant should explain why rather than fail silently. Transparent, human-like communication builds trust and encourages continued use.
فوائد التفاعل متعدد الوسائط
بالنسبة للمستخدمين
Multimodal interfaces deliver freedom of choice. Drivers can control the car hands-free when attention is critical, or use touch when precision matters. This duality makes interaction both safer and more engaging.
Accessibility improves too. Voice helps users with limited mobility or visual impairments, while touch supports those who prefer not to speak or are in noisy environments. The system adapts to the person and the context, not the other way around.
Personalisation further enhances comfort. The assistant can recognise who is driving, recall saved profiles, or suggest routes and music based on routine patterns. Continuous updates add new features, ensuring the experience keeps evolving throughout the vehicle’s lifetime.
للمصنّعين
For OEMs, multimodal HMI is both a differentiator and a strategic asset. It strengthens brand perception as forward-thinking and customer-centric, while providing tangible benefits such as improved user satisfaction and reduced support demand.
Usage data, when collected ethically and with consent, offers powerful insight into how people use in-car systems. It helps identify underused features, refine interfaces and design future functions more efficiently.
وفي الوقت نفسه، تفتح واجهات الإنسان والآلة (HMI) المتقدمة فرصاً تجارية جديدة – من الخدمات المُفعّلة صوتياً واشتراكات الترفيه إلى التكامل السلس مع المنظومات المتصلة.
الخصوصية والأمان والامتثال
نظرًا لأن المساعدات الصوتية تستمع باستمرار لإشارات التنشيط، فإن الخصوصية أمر بالغ الأهمية. يجب أن يعرف المستخدمون متى تُجمع البيانات، وما الذي يُخزَّن، وكيف يُحمى.
A responsible system processes as much as possible on-device, sending only the minimum data required to the cloud – always through encrypted channels. Personal identifiers are removed or tokenised to preserve anonymity.
Visual indicators, such as microphone icons or status lights, should make it clear when the system is listening. Sensitive actions like purchases, account access or factory resets require explicit confirmation.
Compliance with data-protection frameworks such as GDPR is mandatory, but true trust comes from transparency. Allowing users to view or delete their data at any time demonstrates respect for privacy and reinforces long-term loyalty.
تجنب المزالق الشائعة
Even well-intentioned projects can fail if critical details are overlooked. Relying entirely on cloud connectivity leads to downtime in poor coverage areas. Ignoring diverse accents or real-world noise results in recognition failures. And collecting personal data without clear consent risks damaging user trust and regulatory penalties.
تستبق الأنظمة الناجحة هذه المشكلات. فهي تحافظ على قدرات احتياطية تعمل دون اتصال، وتوفر تغذية راجعة متسقة، وتتعامل مع سوء الفهم بسلاسة. وعندما تكون غير متأكد، فمن الأفضل أن تسأل «هل كنت تقصد…؟» من التنفيذ بشكل خاطئ.
وبالمثل، ينبغي أن يتوفر للمستخدمين دائمًا خيار العودة إلى الإدخال باللمس. فينبغي أن يعزز الصوت سهولة الاستخدام، لا أن يحل محل عناصر التحكم الراسخة.
دراسة حالة: Wavey
لدينا Wavey prototype demonstrates how voice and touch can coexist in a single automotive environment. Built on a Qt-based microHMI platform, it integrates AI-driven voice control with responsive touch interfaces for climate, navigation and media.
يمكن للمستخدمين إصدار أوامر مثل«أشعر بحرارة شديدة» or «شغّل بعض موسيقى الجاز» and the system responds instantly while updating the display. Early user tests showed faster task completion and higher satisfaction compared with touch-only interfaces. Participants described the assistant as “natural”, “human-like” and “less distracting”.
The proof of concept also highlighted valuable lessons. Cabin noise and strong accents required acoustic tuning and additional training data. Cloud latency prompted the integration of a hybrid model with local fallback. And subtle UI feedback, like visual confirmations and brief spoken acknowledgements, proved crucial for user confidence.
Wavey validated the potential of multimodal HMI: intuitive, efficient and adaptable. It also reinforced the importance of multidisciplinary collaboration between AI engineers, UX designers and automotive specialists, a hallmark of our development approach.
إلى أين نتجه بعد ذلك
Multimodal HMI is redefining how people interact with technology. By merging touch and voice, supported by AI, it delivers experiences that are not only convenient but also human-centred and safe.
Touch provides precision and visual control; voice adds speed and natural conversation. Together, they make complex systems simpler to use. For developers, the path forward is clear: start with a few high-impact scenarios, pilot them in real-world conditions, monitor results, and expand step by step.
Equally important is transparency around privacy, continuous optimisation and an iterative design process that keeps the user at the centre. When these elements come together, technology becomes invisible, a silent partner that listens, understands and acts intuitively.
التفاعل متعدد الوسائط ليس مجرد مستقبل تجربة المستخدم في المركبات. إنه موجود بالفعل، وهو يحدد وتيرة كيفية تفاعل الناس مع الأنظمة الذكية عبر مختلف القطاعات.


arrow_circle_rightاتصل بنا
تواصل معنا لترى كيف يمكننا دعم مشروعك
برزيميسواف كشيفانيا
مدير واجهة الإنسان والآلة
arrow_circle_right مقالاتنا